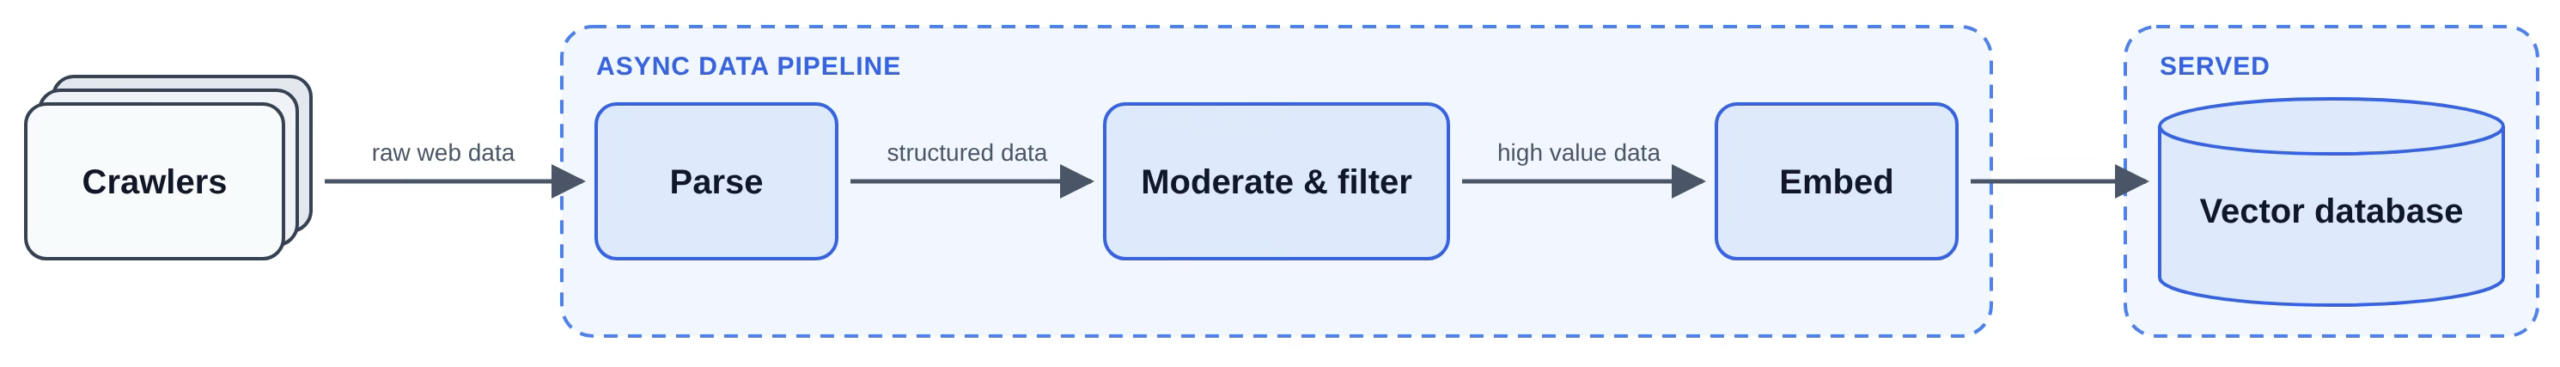
At Exa, we are building one of the few true web indexes by aggregating and serving knowledge from across the web, along with private and synthetic sources. We optimize the index for semantic search, grounding agents and humans in true, high-quality data. We use multi-tower semantic machine learning (ML) models to embed web data and query data into the same vector space, so users can express complex queries in natural language alongside traditional keyword search. The keystone technology behind this is an in-house vector database. It must ingest as much high-quality web data as possible and embed all of it. The unit economics of embedding therefore underlie everything we do. At the scale of tens or hundreds of billions of…
Source: Artificial Intelligence

Leave a Reply