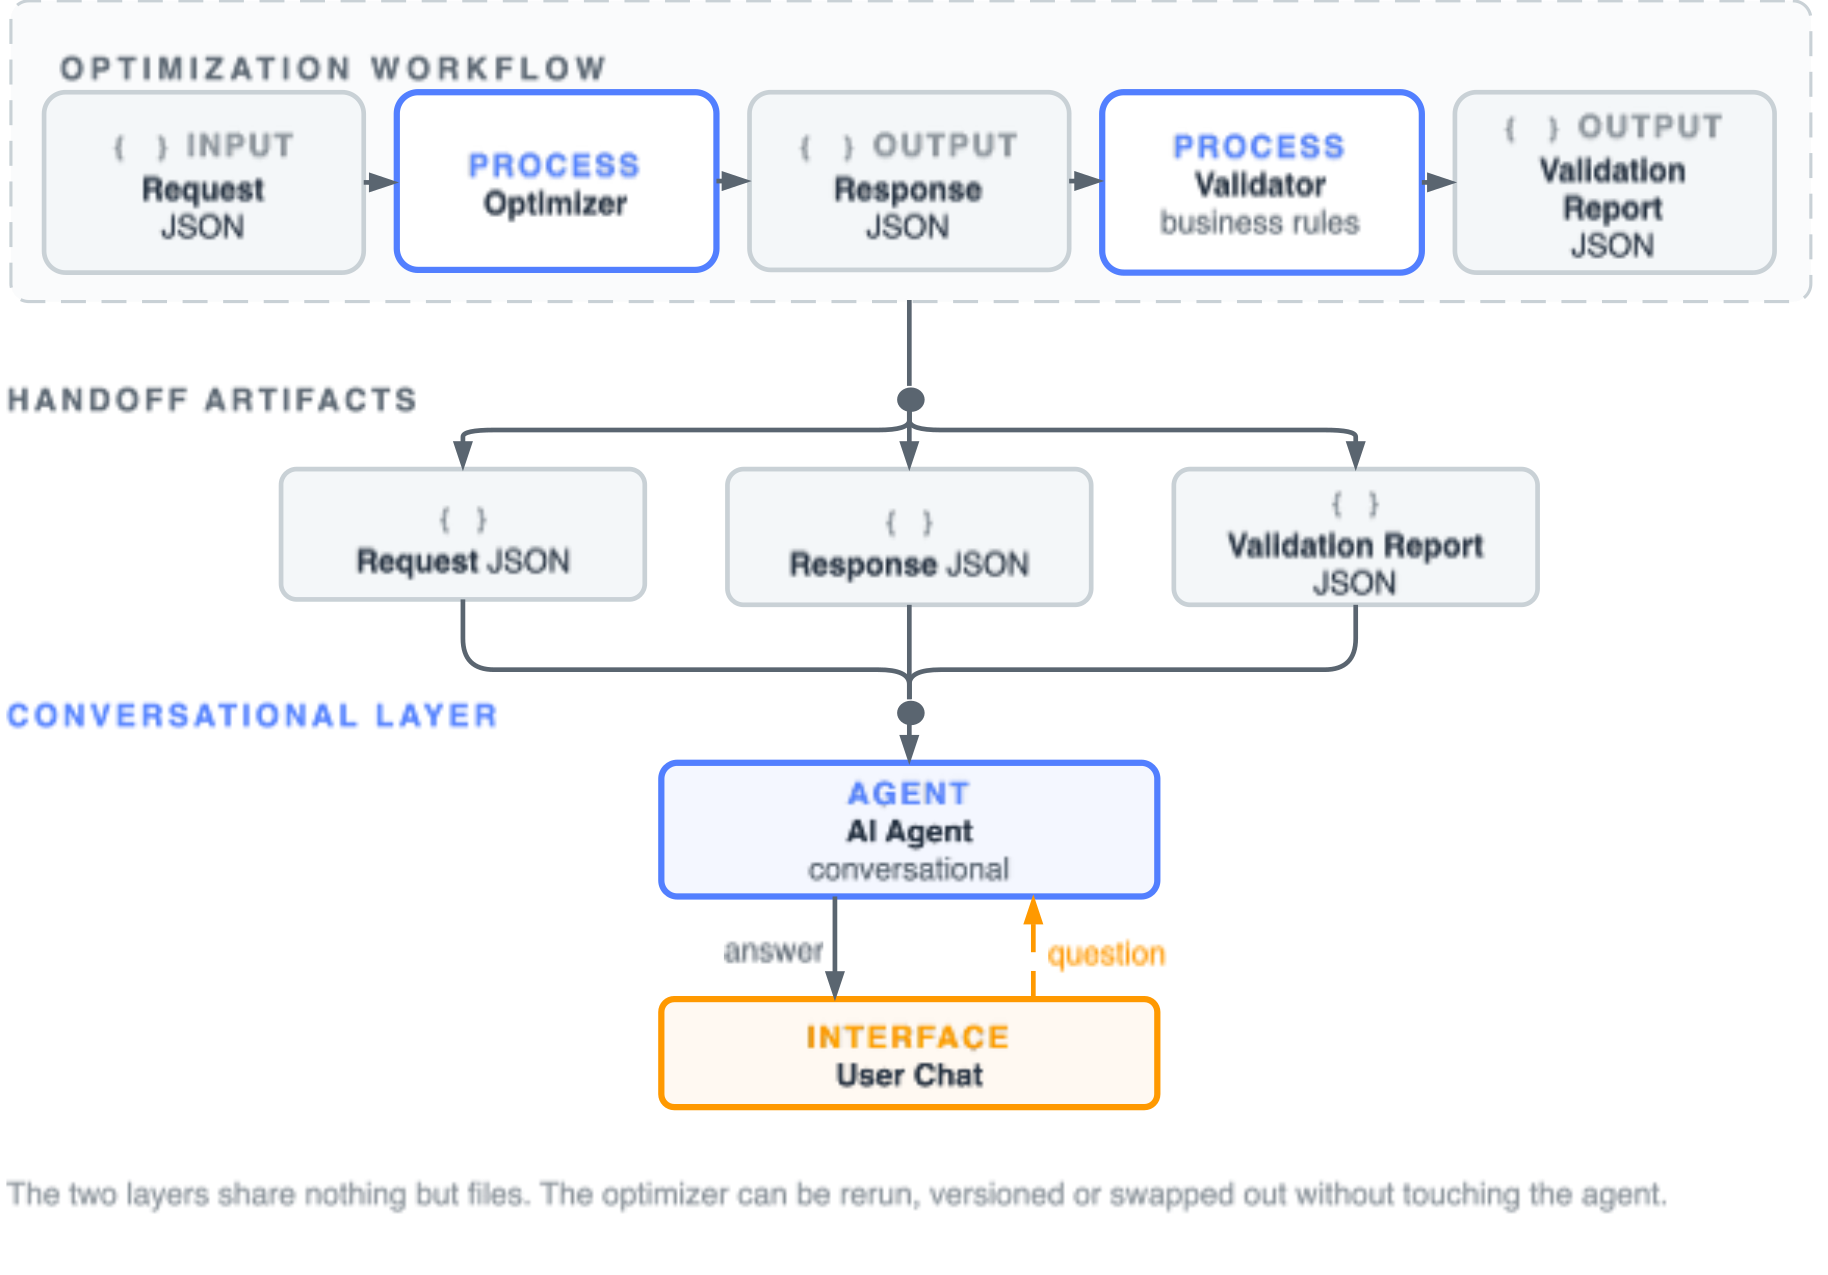
As enterprises build production agents with dozens of tools and large structured inputs, token consumption and latency become the primary blockers to a good user experience. When these agents process large JSON data, every additional tool invocation injects the full payload into the large language model (LLM) context window, causing token usage and response latency to spike. Over multi-turn conversations, this pressure compounds, driving up costs and degrading response quality. Effectively managing context-window pressure in agentic systems is key to reliability and responsiveness at scale. In this post, we share three composable strategies we used to build a production agent for Flightscape that handles 20 MB+ JSON payloads. You can apply them to reduce token costs, lower latency, and maintain…
Source: Artificial Intelligence

Leave a Reply